Skip to content
All articles
7 min read

Nginx 403 Forbidden: 6 Causes and How to Fix Them

MD Rakibul Islam RakibMD Rakibul Islam RakibFull-stack developer, DevOps & Linux engineer
Nginx 403 Forbidden: 6 Causes and How to Fix Them

Nginx 403 Forbidden means Nginx found the request but won't serve it: usually file permissions, a missing index file or a deny rule. The log says which.

A 403 is frustrating because everything looks right. The files are there, the domain resolves, Nginx is running, and still the browser says "403 Forbidden". The good news is that Nginx always writes the reason to its error log, and there are only a handful of reasons. I set up Nginx for every site I deploy, including this one, and the 403s I've fixed for clients almost always came down to the first three causes below. Here's how to find yours in two commands.

Key takeaways

  • Read the log: sudo tail -n 20 /var/log/nginx/error.log. "directory index ... is forbidden" and "(13: Permission denied)" are two different problems with two different fixes.
  • Nginx needs execute permission on every parent folder, not only read permission on the file. namei -l shows the whole path at once.
  • Files in /home/user are the classic trap: home folders are private by default on modern Ubuntu, so Nginx can't walk into them.
  • A folder without index.html returns 403 rather than 404, because listing directories is off by default.
  • Never fix a 403 with chmod 777. Give the Nginx user exactly the access it needs.

Step 1: Find the reason in the error log

sudo tail -n 20 /var/log/nginx/error.log
# reload the page in the browser, then look again, or follow it live:
sudo tail -f /var/log/nginx/error.log

You'll see one of these:

directory index of "/var/www/shop/" is forbidden
open() "/home/deploy/site/index.html" failed (13: Permission denied)
access forbidden by rule, client: 203.0.113.7

No log line at all? Then the 403 isn't coming from your Nginx. Check the response headers with curl -sI https://example.com. If they say server: cloudflare, a Cloudflare WAF or security rule blocked the request, not your server.

Cause 1: "directory index of ... is forbidden"

Nginx was asked for a folder, found no index file in it, and directory listing is off. So it refuses. Check what's actually in the folder and what your config expects:

ls -la /var/www/shop/
grep -nE 'root|index|try_files' /etc/nginx/sites-enabled/shop

Common reasons:

  • The build went somewhere else. Your React or Vite app builds to dist/ but root points at the project folder. Point root at the folder that contains index.html.
  • PHP site without index.php in the index list. Use index index.php index.html;.
  • A single-page app needs try_files $uri $uri/ /index.html; so deep links fall back to the app.
  • The deploy hasn't finished or the upload failed, so the folder is empty.

Cause 2: "(13: Permission denied)"

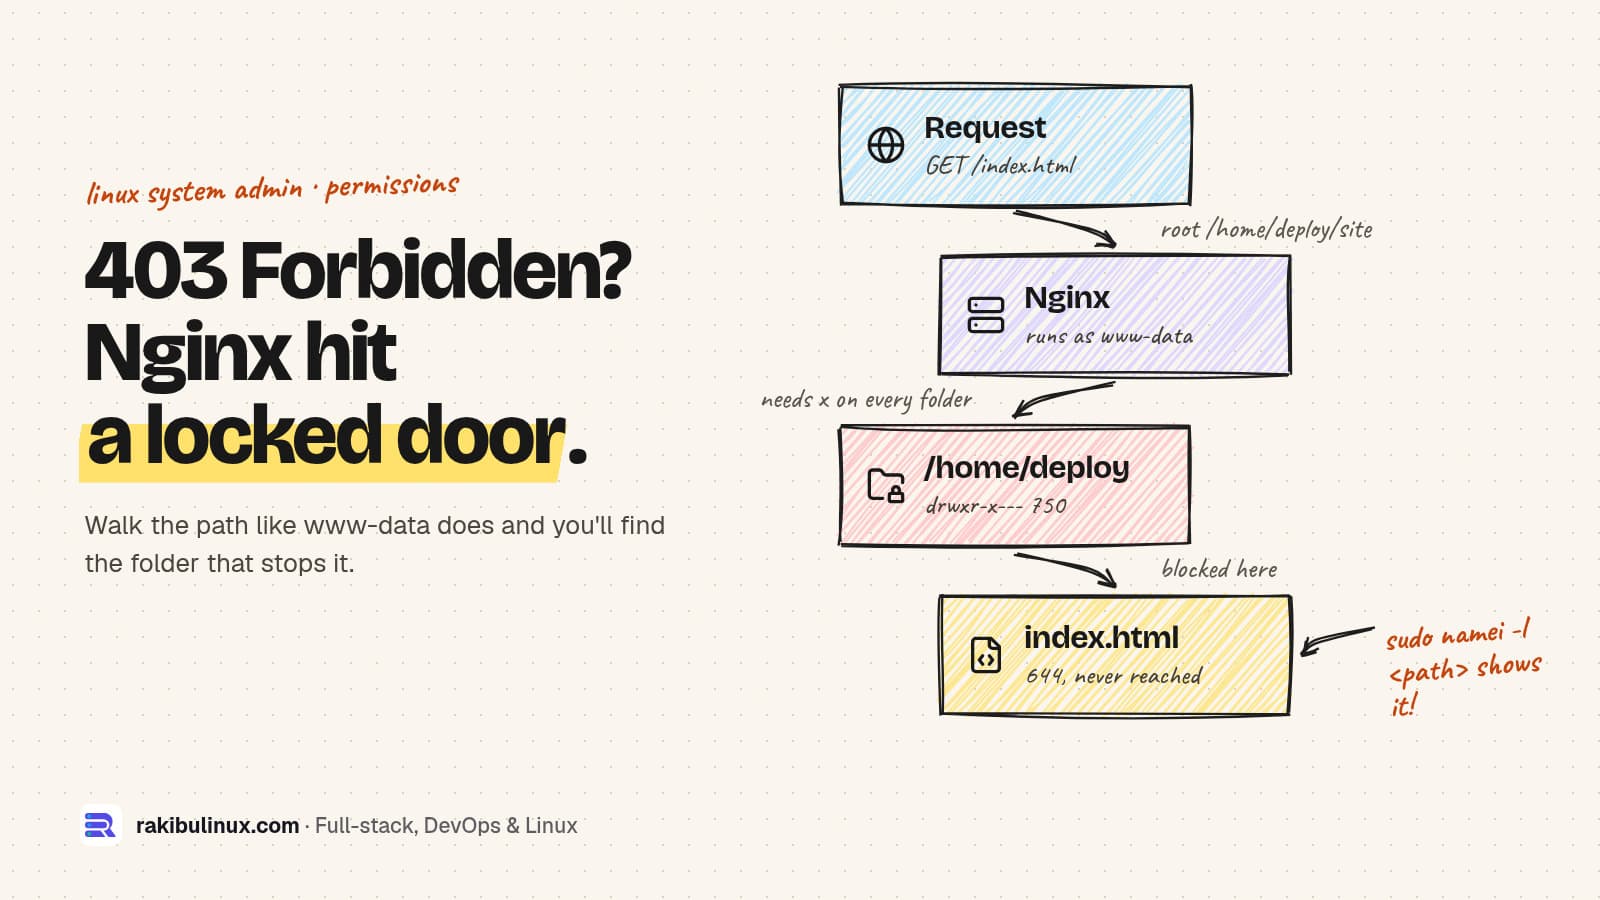
The file exists, but the Nginx worker can't read it. On Ubuntu and Debian Nginx runs as www-data; on RHEL-family systems, as nginx. To read /home/deploy/site/index.html, that user needs execute (x) on every folder in the path and read (r) on the file. One locked folder anywhere in the chain is enough for a 403. This command shows them all:

sudo namei -l /home/deploy/site/index.html
f: /home/deploy/site/index.html
drwxr-xr-x root   root   /
drwxr-xr-x root   root   home
drwxr-x--- deploy deploy deploy      <- www-data can't enter
drwxr-xr-x deploy deploy site
-rw-r--r-- deploy deploy index.html

That middle line is the problem I meet most. Since Ubuntu 21.04, new home folders are created with mode 750, so other users, including www-data, can't pass through. Two clean fixes:

# Best: serve from /var/www, owned by your deploy user, readable by all
sudo mkdir -p /var/www/site
sudo chown -R deploy:deploy /var/www/site
sudo find /var/www/site -type d -exec chmod 755 {} +
sudo find /var/www/site -type f -exec chmod 644 {} +

# Or: let only the www-data group pass through the home folder
sudo chgrp www-data /home/deploy
sudo chmod 750 /home/deploy        # owner rwx, group r-x, others nothing

Test as the Nginx user, which is the real proof:

sudo -u www-data cat /home/deploy/site/index.html > /dev/null && echo readable
/ home deploy site index.html 755 ✓ 755 ✓ 750 ✗ 755 644 403 Forbidden www-data needs x on every folder, r on the file
Nginx's worker user has to pass through every folder in the path. One private folder, here a home directory with mode 750, is enough to turn a perfectly good file into a 403.

Cause 3: "access forbidden by rule"

Your own config blocked the request with deny. Look for allow and deny lines, including in included snippets:

sudo nginx -T 2>/dev/null | grep -nE 'allow|deny'

A common one is an admin area locked to an office IP that changed, or a location ~ /\. rule that also blocks /.well-known/, which breaks Let's Encrypt validation. Add an explicit exception above it: location ^~ /.well-known/acme-challenge/ { allow all; }.

Cause 4: SELinux (Rocky, Alma, RHEL, Fedora)

If permissions look perfect and you're on a Red Hat family system, SELinux is the likely cause. Files you created in your home folder or copied with mv keep the wrong security label. Check and fix the label:

ls -Z /var/www/site
sudo ausearch -m avc -ts recent | tail
sudo semanage fcontext -a -t httpd_sys_content_t "/var/www/site(/.*)?"
sudo restorecon -Rv /var/www/site

Don't disable SELinux to make a 403 go away. Relabelling takes a minute and keeps the protection.

Cause 5: Wrong root or alias

A path mistake can produce a 403 instead of a 404 when it lands on a real folder. The classic is alias without a trailing slash, or using root where you meant alias. With location /static/ { root /var/www/site/static; }, Nginx looks in /var/www/site/static/static/. Use alias /var/www/site/static/; instead, with the slashes matching on both sides.

Cause 6: Uploaded files with wrong ownership

The site works, but new uploads or files deployed by CI return 403. The upload or deploy process created them with a restrictive umask (mode 600 or 700). Check with ls -l, fix with the find ... chmod commands above, and set the umask in your deploy script or app so new files come out as 644. My GitHub Actions deploy sets permissions as part of the release step so this never comes back.

Checklist after the fix

  • Test the config and reload: sudo nginx -t && sudo systemctl reload nginx. If Nginx won't come back, see Job for nginx.service failed.
  • Test as the Nginx user with sudo -u www-data, not as root. Root can read everything, so it proves nothing.
  • Check the next error. If the 403 becomes a 502, the static part is fixed and the app behind Nginx is down: see Nginx 502 Bad Gateway.
  • Keep secrets out of the web root. A 403 on .env or .git is correct. Better still, keep them outside the folder Nginx serves.

Frequently asked questions

What causes 403 Forbidden in Nginx?

Nginx refuses requests it can't or won't serve. The usual causes are a folder without an index file, file or folder permissions that stop the www-data user, a deny rule in the config, or SELinux labels on Red Hat systems. The error log names which one.

Should I chmod 777 to fix a 403?

No. It makes every file writable by any process on the server, so one compromised app can change your whole site. Use 755 for folders and 644 for files, owned by your deploy user, and make sure parent folders are passable.

Why does Nginx return 403 instead of 404 for a missing page?

When the URL maps to a folder that exists but has no index file, Nginx returns 403 because listing the folder is forbidden. A URL that maps to nothing at all returns 404.

How do I enable directory listing in Nginx?

Add autoindex on; inside the location block. Only do this for folders meant to be public, like a downloads area, because it shows every file name in the folder.

Why do I get 403 Forbidden from Cloudflare but not from my server?

If the response header says server: cloudflare and your Nginx log is empty, Cloudflare's firewall, bot protection or a WAF rule blocked the visitor. Check Security, then Events, in the Cloudflare dashboard for the blocked request and the rule that matched.

Need your server set up properly?

I set up Nginx, SSL and permissions on Ubuntu servers so deploys don't break them, and fix 403s and other server errors the same day. See my VPS setup with Nginx and free SSL, all Linux system admin services, or contact me with your domain and the error log line.

MD Rakibul Islam Rakib

Written by

MD Rakibul Islam Rakib

Full-stack developer, DevOps engineer and Linux system administrator with 5+ years of production experience. I deploy, harden and fix servers and web apps for clients worldwide, and everything in this article runs on real servers I manage, including this site.

  • Nginx 403 Forbidden
  • directory index is forbidden
  • 13: Permission denied
  • www-data permissions
  • namei
  • SELinux
  • Ubuntu

Keep reading

WordPress to Next.js Migration Without Losing SEO
Website DesignOct 9, 2026

WordPress to Next.js Migration Without Losing SEO

Moving WordPress to Next.js makes a site faster and safer, but only if you keep every URL, redirect old ones with 301s and carry over titles and meta tags. Business owners usually ask me about this after one of three things: the WordPress site got hacked, it fails Core Web Vitals no matter how many caching plugins they add, or the plugin and hosting bills keep growing. Next.js fixes all three well. This site is a Next.js 16 app, and I've rebuilt WordPress sites this way. But a migration done carelessly can wipe out years of Google rankings in a week. This guide covers when it's worth it, the two ways to do it, and the SEO steps that keep your traffic. Key takeaways Migrate for a reason: speed, security, custom features or cost. If your team lives in the WordPress editor and the site is fine, a headless setup or a tune-up may be better. Two paths: headless (keep WordPress as the editor, Next.js as the website) or full move (content goes into Markdown, a headless CMS or your own database). Crawl the old site first and keep a list of every URL. That list is your redirect map and your checklist. Keep URLs identical where you can. Where they must change, add one 301 redirect per old URL, never a blanket redirect to the homepage. Carry over titles, meta descriptions, alt text and structured data , then watch Search Console for a few weeks. Is it worth moving off WordPress? Good reasons to migrate: Speed. A Next.js site sends pre-rendered HTML and only the JavaScript a page needs. Page-builder themes often load large CSS and script bundles on every page. Faster pages help rankings and conversions; see my guides on fixing slow LCP and INP . Security. Most WordPress hacks I've cleaned up came through an outdated plugin or theme. A Next.js site has no public admin login and no plugin folder to attack. Custom features. Booking, dashboards, customer portals and integrations are normal code in Next.js, not a stack of plugins fighting each other. Running costs. No premium plugin licences to renew, and a fast site runs on a small VPS. My hosting cost comparison shows the options. Reasons to wait: non-technical editors who rely on the WordPress editor daily, a WooCommerce shop with many extensions you'd have to replace, or a site that already performs well. Changing technology doesn't fix weak content or an unclear offer. Path 1: Headless WordPress WordPress stays where your team writes, and Next.js becomes the public website. Next.js reads posts and pages from the built-in REST API ( /wp-json/wp/v2/posts ) or from the WPGraphQL plugin: // app/blog/[slug]/page.tsx import { notFound } from 'next/navigation'; const WP = 'https://cms.example.com/wp-json/wp/v2'; export default async function Post({ params }: { params: Promise<{ slug: string }> }) { const { slug } = await params; const res = await fetch(`${WP}/posts?slug=${slug}&_embed`, { next: { revalidate: 300 } }); const [post] = await res.json(); if (!post) notFound(); return <article dangerouslySetInnerHTML={{ __html: post.content.rendered }} />; } Editors keep their workflow, and the slow, plugin-heavy front end disappears. Move WordPress to a subdomain such as cms.example.com , block it from search engines, and protect its login. The catch: you now run two systems, and page-builder layouts don't come across, because Next.js renders the content, not the builder. Path 2: Full migration Export the content once and switch WordPress off. Content goes into Markdown or MDX files in the repo (great for small, developer-run sites), a headless CMS such as Sanity, Strapi or Payload, or your own database with an admin dashboard, which is how this site works. Pull everything through the REST API with a script, convert the HTML, download the media, and keep each post's slug, date, title, excerpt and SEO fields. You end up with one system, fewer moving parts, and nothing left to patch every week. Every URL from the old site needs a destination: the same path, or a 301 redirect to its new address. Old URLs left without one return 404s, and the rankings they earned disappear with them. The SEO checklist that protects your rankings 1. Inventory every URL before you touch anything Export the old site's URLs from three places: the XML sitemap (Yoast and Rank Math put it at /sitemap_index.xml ; core WordPress at /wp-sitemap.xml ), a crawl with a tool like Screaming Frog, and Search Console's Pages and Performance reports. Mark the pages that get traffic or backlinks. Those must not break. 2. Keep the same URLs Next.js routes can match almost any WordPress structure. If posts lived at /my-post/ , use an app/[slug]/page.tsx route. If you want cleaner URLs, change them on purpose and redirect, not by accident. Watch trailing slashes: WordPress adds them, Next.js doesn't by default. Set trailingSlash: true in next.config.ts if you keep the old style. 3. Redirect what changes // next.config.ts export default { async redirects() { return [ { source: '/:year(\\d{4})/:month(\\d{2})/:slug', destination: '/blog/:slug', permanent: true }, { source: '/category/:cat', destination: '/blog?topic=:cat', permanent: true }, { source: '/feed', destination: '/rss.xml', permanent: true }, ]; }, }; permanent: true sends a 308, which search engines treat like a 301. For hundreds of one-off URLs, keep them in a map file or do them in Nginx. Never redirect everything to the homepage. Google treats that as a soft 404 and drops the rankings anyway. 4. Carry over the SEO data Export the title and meta description from your SEO plugin for every page, and set them with generateMetadata . Keep image alt text, canonical tags, Open Graph images, and structured data such as Article, FAQ, Product and LocalBusiness. Generate a sitemap with app/sitemap.ts and a robots.ts . 5. Don't forget the hidden features Contact forms (and their spam protection and email delivery, see emails going to spam ), the search box, comments, RSS, analytics, cookie consent and newsletter embeds. List every plugin and decide what replaces each one. 6. Launch, then watch Switch DNS when traffic is lowest, keep the old server running for a few days, then submit the new sitemap and test key URLs in Search Console. Crawl the old URL list against the new site and expect a 200 or a single 301 for every one, never a 404 or a redirect chain. My zero-downtime migration guide covers the DNS cutover, and redesign without losing SEO has the full checklist. Frequently asked questions Is Next.js better than WordPress for SEO? Next.js makes it easier to build fast pages with clean HTML, which helps Core Web Vitals. But rankings come from content, links and technical basics. A well-optimised WordPress site can outrank a careless Next.js one, so the migration must preserve URLs and metadata. Will I lose rankings when moving from WordPress to Next.js? Not if you keep URLs the same or 301-redirect every changed one, keep titles and meta descriptions, and keep the content. A short wobble for a few weeks is normal while Google recrawls. Big drops come from missing redirects. Can I keep using WordPress as a CMS with Next.js? Yes. That's headless WordPress: editors use the normal admin, and Next.js reads content through the REST API or WPGraphQL and renders the public site. Keep the WordPress admin off the public domain and updated. How long does a WordPress to Next.js migration take? A small business site of 10 to 30 pages is usually a few weeks including design, content transfer, redirects and testing. Large blogs, multilingual sites and WooCommerce shops take longer because there's more content and functionality to rebuild. What about WooCommerce? You can run WooCommerce headless or move to a commerce platform with an API, but checkout, payments, shipping and extensions all need to be rebuilt or replaced. Plan and price that part separately; it's usually most of the work. Thinking about leaving WordPress? I rebuild WordPress sites in Next.js with every URL, redirect and meta tag carried over, so you get the speed without losing your Google traffic. See my business website design and development service, all website design services , or send me your site for an honest opinion on whether it's worth it.

Read article →
Website "Not Secure" With SSL? Fix Mixed Content
Website DesignOct 9, 2026

Website "Not Secure" With SSL? Fix Mixed Content

A site that shows "Not secure" with a valid SSL certificate is loading something over http://. Find it in the browser console, then switch those URLs to https. You installed an SSL certificate, the address starts with https:// , and the browser still shows "Not secure" or a broken padlock. Visitors notice. Some leave, and a contact or checkout form that looks unsafe loses leads. This is almost always mixed content : the page itself is secure, but it loads an image, script, font or form target over plain http:// . I fix this during server moves and redesigns all the time, and it takes three steps: find the insecure URLs, fix them at the source, then add a safety net so new ones can't slip in. Key takeaways Open DevTools (F12) → Console. Every insecure resource is listed as a "Mixed Content" warning with its exact URL. Scripts, stylesheets and iframes over http are blocked , which can break menus, sliders and forms, not only the padlock. The real fix is changing http:// to https:// where the URL lives: the database, theme files, CSS, or a hard-coded embed. A form that submits to http:// makes Chrome warn on submit. Check every form's action . Add upgrade-insecure-requests as a safety net, and redirect all http traffic to https. Step 1: Find every insecure resource Open the page in Chrome, press F12, and go to the Console tab. Reload. Mixed content shows up like this: Mixed Content: The page at 'https://example.com/' was loaded over HTTPS, but requested an insecure script 'http://example.com/wp-content/plugins/slider/slider.js'. This request has been blocked; the content must be served over HTTPS. The Security tab in DevTools gives a summary for the page. Check more than the homepage: blog posts, the shop, the contact page and checkout often load different files. To scan from a terminal, search the raw HTML for http:// in the attributes that load things: curl -s https://example.com/ | grep -oE '(src|href|action|srcset)="http://[^"]+"' | sort -u curl -s https://example.com/wp-content/themes/mytheme/style.css | grep -o 'url(http://[^)]*' | sort -u Plain links to other sites ( <a href="http://..."> ) don't cause mixed content, though it's still worth updating them. What matters is anything the page loads : images, scripts, styles, fonts, iframes, video, and form targets. Why browsers treat it differently Browsers split mixed content into two kinds. For images, audio and video, Chrome first tries to load the same URL over https automatically, and only blocks it if that fails. Scripts, stylesheets, iframes and fetch requests are blocked outright, because an attacker on the network could change them and take over the page. That's why mixed content can do more than remove the padlock: a blocked jQuery or stylesheet can break the whole layout. Browsers upgrade insecure images and media to https when they can, but block insecure scripts, styles and iframes completely. One http script can remove the padlock and break a menu or a form at the same time. Step 2: Fix the URLs at the source WordPress Old http:// URLs live in the database: in post content, widget settings, theme options and page builder data. First set both addresses under Settings → General to https:// . Then replace the rest with WP-CLI, which handles serialized data safely (a plain SQL replace can corrupt it): wp db export before-https.sql # backup first wp search-replace 'http://example.com' 'https://example.com' --skip-columns=guid --dry-run wp search-replace 'http://example.com' 'https://example.com' --skip-columns=guid wp cache flush Run the dry run first and read the counts. If you use a caching plugin or a CDN, purge it afterwards, or visitors keep seeing the old HTML. Hard-coded URLs in themes, CSS and templates Search the code for http:// and change your own domain's URLs to https or to relative paths ( /images/logo.png ): grep -rn "http://" --include=*.{php,html,css,js,tsx} ./theme ./src | grep -v "http://www.w3.org" For third-party files (an old widget, font or analytics script), switch to the provider's https URL. If a provider doesn't support https at all in 2026, replace it. It's also a security risk. Forms Check the action of every form, including newsletter embeds. A form posting to http:// makes Chrome show a warning when the visitor submits, which kills conversions on contact and checkout pages. Step 3: "Not secure" but no mixed content? If the console is clean, look at these instead: Your app thinks it's on http. Behind Nginx, a load balancer or Cloudflare, the app sees plain http and builds http:// links. Pass proxy_set_header X-Forwarded-Proto $scheme; in Nginx and make the app trust it. In WordPress behind a proxy, check $_SERVER['HTTPS'] handling in wp-config.php . Cloudflare "Flexible" SSL. Browser to Cloudflare is encrypted, Cloudflare to your server isn't, and it often causes redirect loops. Install a certificate on the origin and use "Full (strict)". My too many redirects guide covers this. The certificate itself. Expired, issued for a different name (www vs non-www), or missing its chain. Click the padlock area to see the reason, and see Certbot renewal failed if it expired. Step 4: Add a safety net Redirect all http traffic to https with one 301, and tell browsers to upgrade any leftover http requests. In Nginx: server { listen 80; server_name example.com www.example.com; return 301 https://www.example.com$request_uri; } # inside the https server block: add_header Content-Security-Policy "upgrade-insecure-requests" always; add_header Strict-Transport-Security "max-age=31536000" always; upgrade-insecure-requests makes the browser fetch every http:// resource on the page over https. It hides problems rather than fixing them, so do it after step 2, not instead of it. HSTS tells browsers to always use https for your domain. Start with a short max-age if you're not sure every subdomain has a certificate. Does mixed content hurt SEO? HTTPS is a Google ranking signal, and Google's page experience guidance expects pages served securely. More directly, a "Not secure" warning and broken scripts hurt trust and conversions. If you just moved to https, also check that canonical tags, the sitemap and internal links all use the https URLs. My redesign without losing SEO checklist covers the redirect side, and crawled, currently not indexed helps if pages drop out afterwards. Frequently asked questions Why does my website say "Not secure" when I have SSL? The page loads at least one resource over plain http, which is called mixed content, or the certificate has a problem such as being expired or issued for a different domain. The browser console lists any mixed content URLs. How do I find mixed content on my website? Open Chrome DevTools with F12, go to the Console and reload the page. Each insecure resource appears as a "Mixed Content" warning with its URL. Repeat on your main templates: home, blog post, product, contact and checkout. Is upgrade-insecure-requests enough to fix mixed content? It's a good safety net, but it only works if every resource is also available over https. Fix the URLs at the source first, then keep the header to catch anything you missed. How do I fix mixed content in WordPress? Set the WordPress and Site Address to https under Settings, then run wp search-replace from http to https with a backup and a dry run first. Fix any remaining hard-coded URLs in the theme or plugins and purge caches. Does mixed content affect Google rankings? HTTPS is a lightweight ranking signal, and mixed content weakens it. The bigger cost is lost trust: browser warnings and broken scripts make visitors leave and stop forms from converting. Want a secure, fast site that converts? I fix SSL, mixed content and redirect problems, and build business websites that are secure and SEO-ready from day one. See my technical SEO audit and fix , all website design services , or send me your URL .

Read article →
Emails Going to Spam? Fix SPF, DKIM and DMARC (2026)
Linux System AdminOct 9, 2026

Emails Going to Spam? Fix SPF, DKIM and DMARC (2026)

Business emails land in spam mostly because SPF, DKIM or DMARC is missing or broken. Gmail's "Show original" shows which one fails; fix it in your DNS. When your quotes, invoices or contact-form replies go to spam, you lose customers without ever knowing it. Gmail, Yahoo and Outlook now expect every sender to prove the email really comes from their domain, and they're strict about it. I set up DNS and mail for the sites I build and host, and when a client tells me "customers say they never got our email", the cause is nearly always one of the authentication records below, or a contact form that pretends to send from the visitor's address. Here's how to check yours in five minutes and fix it. Key takeaways Check a real message first. In Gmail, open it, click the three dots, then "Show original". It shows PASS or FAIL for SPF, DKIM and DMARC. SPF lists which servers may send for your domain. One record only, and every service you send through must be in it. DKIM signs each email. Turn it on in every service that sends for you: Google Workspace, Microsoft 365, your newsletter tool, your app's email provider. DMARC ties them together and tells inboxes what to do with failures. Start with p=none and reports, then tighten. Contact forms must send from your own domain and put the visitor's address in Reply-To , never in From . Why inboxes got strict Since February 2024, Gmail and Yahoo require every sender to have SPF or DKIM, and bulk senders (about 5,000 or more messages a day to Gmail) to have SPF, DKIM and DMARC, one-click unsubscribe for marketing mail, and a spam complaint rate under 0.3%. Microsoft started enforcing similar rules for Outlook.com, Hotmail and Live in May 2025. You may not be a bulk sender, but the same checks decide where your emails land. Unauthenticated mail is the first thing filters push to spam. Step 1: Read the verdict on a real email Send an email from your business address to a Gmail account. Open it, then three dots → Show original . At the top you'll see: SPF: PASS with IP 209.85.220.41 DKIM: 'PASS' with domain example.com DMARC: 'PASS' Any FAIL, NEUTRAL or a missing line tells you where to start. Do this for every way your business sends email: your mailbox, your website's contact form, your shop's order emails, your newsletter. They're often different systems, and each needs its own setup. From a terminal you can read the records directly: dig +short TXT example.com | grep spf dig +short TXT _dmarc.example.com dig +short TXT google._domainkey.example.com # selector depends on the provider Step 2: Fix SPF SPF is a TXT record on your domain listing who may send for it. A typical one for Google Workspace plus a transactional email service: example.com. TXT "v=spf1 include:_spf.google.com include:amazonses.com ~all" Mistakes I find all the time: Two SPF records. Adding a second v=spf1 record for a new service breaks both. Merge them into one record. A sending service not listed. Your CRM or invoicing tool sends as your domain but isn't in the record. Check each tool's docs for its include: value. More than 10 DNS lookups. Each include can trigger several lookups, and past 10 SPF fails with a "permerror". Remove services you no longer use. Ending with +all , which lets anyone send as you. Use ~all (soft fail) or -all . Step 3: Turn on DKIM everywhere DKIM adds a digital signature to every email. The sending service gives you a public key to publish in DNS, usually as a TXT or CNAME record under selector._domainkey.example.com , and then you switch signing on in its admin panel. In Google Workspace it's under Apps → Gmail → Authenticate email; Microsoft 365 has it in the Defender portal. Google Workspace doesn't sign with your domain until you publish the record and click "Start authentication". That last click is the step people miss. Do the same for each service that sends as your domain. DKIM is what survives forwarding, so it matters more than SPF in practice. Receiving inboxes check that the sending server is allowed (SPF), that the message is signed by your domain (DKIM), and that both match the From address (DMARC). Pass all three and the email has a fair chance at the inbox. Step 4: Add DMARC DMARC tells receivers what to do when SPF and DKIM don't line up with the domain in the From address, and sends you reports. Start in monitor mode: _dmarc.example.com. TXT "v=DMARC1; p=none; rua=mailto:dmarc@example.com" After two to four weeks of reports showing all your legitimate senders pass, move to p=quarantine , then p=reject . That also stops scammers from sending fake invoices in your name. The raw reports are XML; a free DMARC report viewer makes them readable. Step 5: Fix your website's contact form This one is behind most "website emails go to spam" complaints I see. The form sends a message to you from the visitor's address, for example From: jane@gmail.com , through your web server. Gmail checks Gmail's DMARC policy, sees a server that isn't Gmail, and rejects or junks it. The correct setup: From: Website <forms@example.com> # your domain, authenticated To: sales@example.com Reply-To: jane@gmail.com # the visitor, so "Reply" still works And send through a proper email API or SMTP service (Amazon SES, Postmark, Resend, Brevo, or your Google Workspace account) with SPF and DKIM set up for example.com , not through PHP's mail() on the web server. Step 6: If you send from your own VPS Running your own mail server is possible, but it's the hardest path. Check these before blaming DNS: Port 25 is often blocked for outgoing mail by cloud providers by default. You may need to request unblocking. Reverse DNS (PTR) for the server's IP must point to a hostname that points back to the same IP. Set it in your VPS provider's panel. IP reputation. A new or previously abused IP starts with a bad reputation. Check it against blocklists, and use TLS for every connection. For most small businesses, a mailbox provider for people and a transactional email service for the website is cheaper than the hours a self-hosted mail server costs. My Cloudflare VPS setup checklist covers the DNS side of a new server, including not proxying mail records. Content and list habits still matter Only email people who asked , and make unsubscribing one click. Complaints hurt more than anything else. Separate marketing from transactional mail , for example newsletters from news.example.com , so a campaign can't drag down your invoices. Avoid link shorteners and image-only emails , and keep the visible link text matching the real URL. Watch Google Postmaster Tools once you send regularly. It shows your spam rate and domain reputation at Gmail. Frequently asked questions Why are my emails going to spam? The most common reasons are missing or broken SPF, DKIM or DMARC records, a contact form sending as the visitor's address, a poor sending IP, or recipients marking your mail as spam. Gmail's "Show original" tells you which authentication check fails. Do I need SPF, DKIM and DMARC? Yes, all three. Gmail and Yahoo require at least SPF or DKIM from every sender and all three from bulk senders, and Microsoft enforces similar rules. Without them your email is much more likely to be filtered or rejected. Can I have two SPF records? No. A domain with two v=spf1 records fails SPF entirely. Combine all senders into one record with several include: entries, and stay under 10 DNS lookups. How long do DNS changes for SPF, DKIM and DMARC take? Usually minutes to a few hours, depending on the record's TTL. Test with dig or an online checker, then send a fresh email and check "Show original" again. Old emails won't change. Why do my website contact form emails go to spam? Usually the form sends from the visitor's email address through your web server, which fails their domain's DMARC check. Send from your own domain through an authenticated email service and put the visitor's address in Reply-To. Want your emails in the inbox? I set up domains, DNS, SPF, DKIM, DMARC and website email sending for small businesses, and fix contact forms that lose leads. See my business website service , all Linux system admin services , or send me your domain and I'll check your records.

Read article →